Choosing a Data Masking Tool
A data masking tool can be an effective, if not essential, way to protect sensitive information stored in files and databases. As data breaches, lawsuits, and privacy regulations continue to create challenges for organizations, companies must find ways to anonymize production and test data without sacrificing its utility for analytics, research, marketing, or software development.
Since IRI introduced data masking in files off the mainframe in 2007, first through CoSort and later with the release of FieldShield in 2011, many other vendors have entered the market. Today, data masking tools compete in static and dynamic masking environments across structured, semi-structured, and unstructured data sources.
Choosing the right tool requires more than comparing masking functions. Organizations must also consider data discovery, scalability, integration, compliance, and long-term operating costs. This article examines the key requirements and evaluation criteria for selecting a data masking tool that aligns with your organization’s data security and privacy needs.
Understanding Requirements
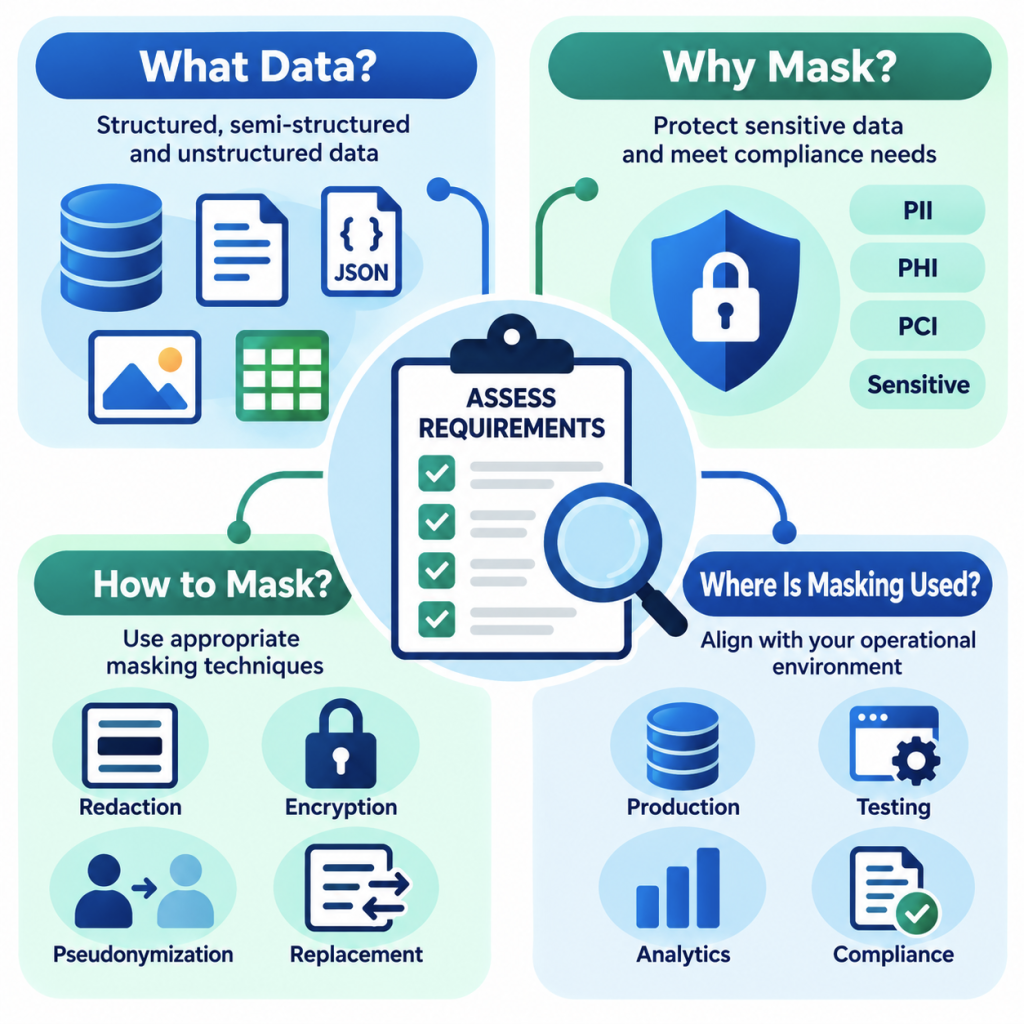
Before evaluating data masking solutions, assess what data you have, why it must be masked, how it should be protected, and where masking fits into your operational environment.
Data masking involves concealing or replacing sensitive information using techniques appropriate to the data and its intended use. Depending on the technique, organizations may need to preserve realistic values, maintain data relationships, or prevent sensitive information from being recovered.
Requirements can vary significantly between production systems, software testing, analytics, and compliance workflows. Start by answering the following questions.
What Type of Data Needs Masking?
Determine whether sensitive information resides in structured, semi-structured, or unstructured data sources.
- Structured data: Relational databases, spreadsheets, and other sources with defined data structures.
- Semi-structured data: NoSQL databases, EDI files, and other formats with partially defined structures.
- Unstructured data: Raw text, documents, images, and other sources without a conventional tabular structure.
You should also identify where the data resides, whether on-premises, in the cloud, or across multiple systems and data silos.
Consider who owns the source data, which systems access it, and where the masked output must be delivered. These factors shape the tool’s discovery, masking, and integration capabilities.
How Should the Data Be Masked?
The intended use of masked data, applicable business rules, and privacy regulations typically determine which masking functions apply to particular data types or classes. For example, you may need to de-identify protected health information (PHI) irreversibly through redaction. Alternatively, you might generalize sensitive values through binning to balance privacy protection with data utility.
For test databases, deterministic masking may be necessary to preserve consistent values across tables or systems, particularly when maintaining referential integrity. Other requirements may call for realistic pseudonymized values or format-preserving encryption. These approaches introduce additional considerations, including reversibility, re-identification risks, and encryption key management.
The appropriate masking method therefore depends on both the sensitivity of the source information and how the resulting data will be used.
When Is the Source Data Updated?
Some datasets remain relatively static, while others are refreshed regularly or require masking as information is processed. Evaluate whether the tool supports the masking framework needed for your environment, including static data masking, dynamic masking, or workflows that process frequently updated data.
The selected solution should fit your operational processes, including development, testing, and DevOps pipelines, without introducing unnecessary complexity.
Are There Specific Compliance Requirements?
Determine which privacy laws, regulations, and industry standards apply to the information being processed. These may include the General Data Protection Regulation (GDPR), the Health Insurance Portability and Accountability Act (HIPAA), or other applicable requirements.
Compliance considerations extend beyond the availability of masking functions. Organizations may also need to discover and locate personal information to respond to Data Subject Access Requests (DSARs), including requests involving the right to erasure.
A data masking tool’s discovery capabilities can therefore be as important as its masking functions when supporting data privacy and compliance processes. Understanding these requirements provides a practical framework for comparing available solutions. The goal is to select a tool that masks data appropriately while fitting into existing operational and security practices.
Data Masking Tool Evaluation Criteria
After defining your masking requirements, evaluate prospective tools based on their features and functions, usability, processing efficiency, integration capabilities, compliance support, and short- and long-term costs.
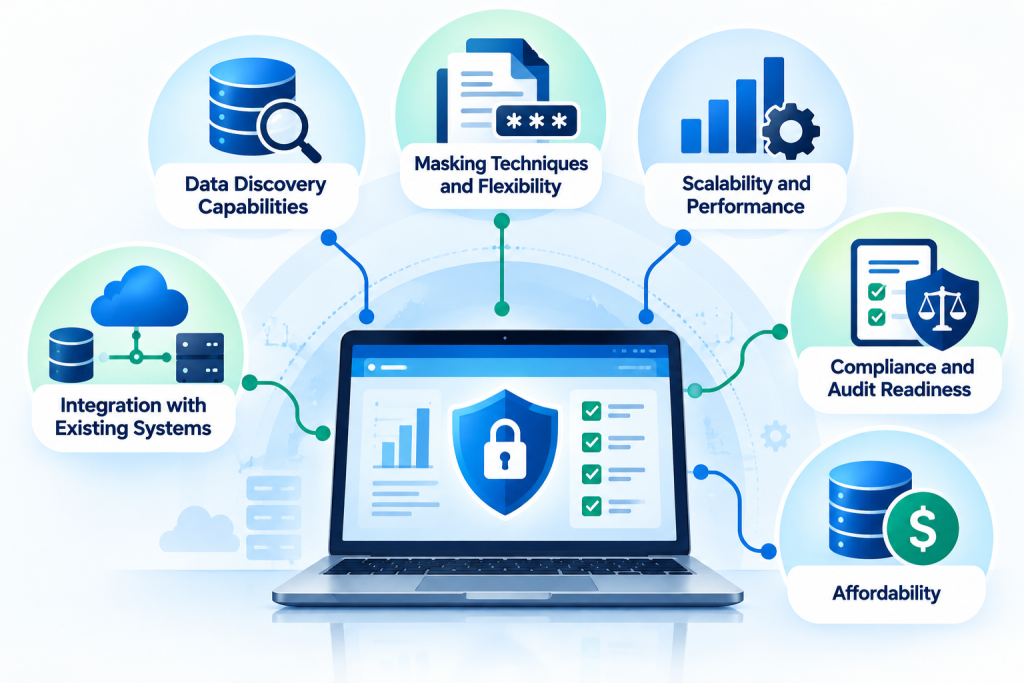
The following six criteria provide a structured approach to comparing data masking solutions.
1. Data Discovery Capabilities
Before sensitive data can be masked, it must be located and identified. Look for tools with data discovery capabilities that include pattern matching, metadata analysis, signature detection, and support for different data source types.
A comprehensive evaluation should consider whether the solution can scan:
- Relational databases and other structured data sources
- Legacy data files
- PDF and Microsoft Office documents
- Images containing sensitive information
- Raw text, application logs, and other unstructured content
The ability to discover sensitive information across structured, semi-structured, and unstructured sources helps organizations identify data that requires protection. Discovery coverage is particularly important when sensitive values are distributed across multiple repositories, applications, or storage environments.
2. Masking Techniques and Flexibility
Different data protection requirements call for different masking techniques.
A data masking tool should provide the functions necessary for your specific use cases, including:
- Static data masking: Masking data stored or copied into non-production environments while preserving the realism and relationships required for testing.
- Deterministic masking: Producing consistent masked values for the same source values when consistency is required across tables, files, or systems.
- Dynamic data masking: Concealing sensitive information in real-time application or data-access contexts.
- Format-preserving masking or encryption: Protecting sensitive values while maintaining required data formats or structures.
- Pseudonymization: Replacing identifying information with pseudonyms while accounting for any retained means of re-identification.
- Redaction, blurring, and generalization: Concealing or reducing sensitive details where irreversible removal or limited disclosure is required.
Some applications may also involve streaming data or masking operations performed within automated processing workflows. When comparing these methods, consider whether masked values must remain realistic, retain their original format, preserve relationships, or support authorized reversal.
For example, deterministic masking can help maintain referential consistency between related database tables. However, not every masking method provides the same level of irreversibility or protection against re-identification.
The tool should support masking techniques that match your security, compliance, and data utility requirements. For additional information, see IRI’s static data masking solution.
3. Scalability and Performance
Whether an organization needs to mask a few database tables, large files, or an entire data lake, processing performance matters. Evaluate how effectively each tool handles the volume, complexity, and variety of your datasets. Important considerations include:
- Processing speed for large datasets
- Parallel processing support
- Performance across different file formats and data sources
- Resource requirements for masking jobs
- Ability to scale as data volumes and operational workloads increase
Lightweight solutions may perform adequately with smaller datasets but may fall short in larger or more complex environments. Where possible, test prospective solutions using representative data volumes and the hardware or infrastructure planned for deployment.
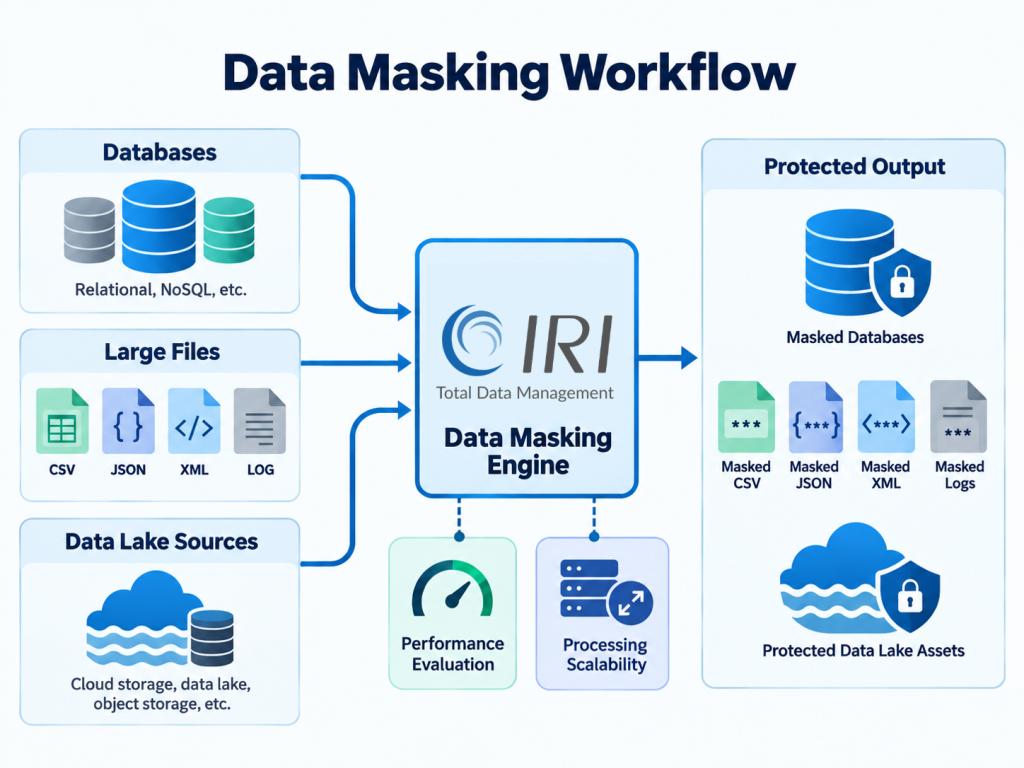
4. Integration with Existing Systems
A data masking tool should work with your existing data infrastructure rather than require unnecessary changes to established processes. Evaluate compatibility with the platforms and systems your organization uses, including:
- Relational databases
- Hadoop environments
- Cloud platforms
- Legacy file systems
- Other structured and unstructured data repositories
Support for multiple data sources can simplify masking across heterogeneous environments.
Also consider whether the tool supports automation through scripts, command-line execution, or APIs, where these capabilities are required. Such integration options may allow masking processes to become part of existing data management, development, and DevOps workflows.
5. Compliance and Audit Readiness
Data masking tools should support the security controls and accountability required by your organization’s privacy and compliance policies. Consider whether an on-premises or self-hosted deployment would help keep sensitive information within your firewall or applicable regional boundaries.
Other evaluation factors include:
- Data discovery and masking audit trails
- Job execution logging
- Re-identification risk scoring capabilities
- Role-based access controls (RBACs)
- Controls governing access to sensitive information and changes to masking rules
These capabilities can help organizations demonstrate that data protection processes are being managed and documented. Audit information may also help identify which searches and masking jobs were performed, while access controls can restrict who is authorized to view data or modify protection settings.
The required controls will depend on your organization’s regulatory obligations and internal security policies.
6. Affordability
Even a technically suitable data masking solution may not be practical if its total cost exceeds your organization’s budget. Evaluate both initial and ongoing expenses, including:
- Software licensing fees
- Maintenance and technical support
- Customization requirements
- Product upgrades and enhancements
- Costs associated with implementation and long-term operation
Consider these expenses alongside the solution’s expected value and return on investment. The objective is to select a tool that satisfies current technical requirements while remaining financially sustainable as your organization’s masking needs evolve.
The Final Decision
Selecting a data masking tool ultimately requires balancing the evaluation criteria against your organization’s priorities, infrastructure, and anticipated data protection needs.
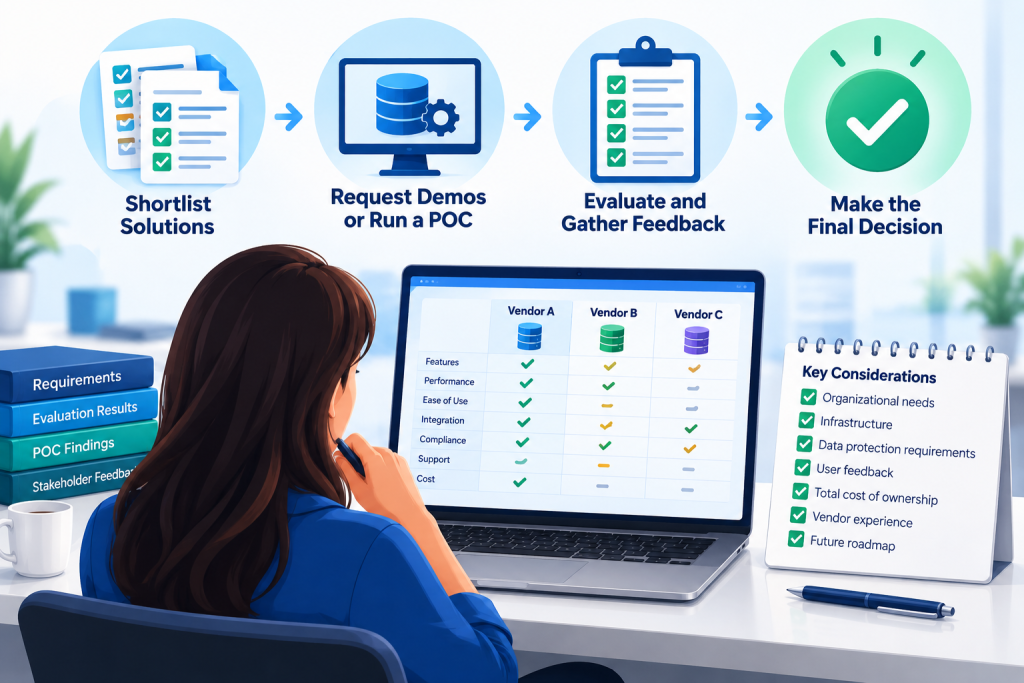
Most organizations begin by developing a shortlist of solutions based on their requirements and evaluation rankings. They can then request demonstrations, trial versions, or proof-of-concept (POC) evaluations.
Many vendors offer pilot programs that allow organizations to mask sample datasets. A POC can help assess a tool’s speed, accuracy, and practical suitability when deployed with your specific combination of data, hardware, and users.
During this evaluation, consider the operational impact of implementation activities, such as installation, configuration, performance tuning, and auditing. Gather feedback from those who will use the tool, as well as stakeholders affected by its outputs, costs, and functionality. This feedback can reveal potential limitations, extensibility requirements, or operational concerns before a broader deployment.
Beyond the product itself, assess the vendor’s experience in data masking and data management. Review its product roadmap, technical support, and commitment to ongoing development and problem-solving. A vendor that develops and maintains its own technology, and can customize it to address specific requirements, may be better positioned to support evolving organizational needs.
Planned product enhancements may not address immediate requirements, but they can indicate how well a vendor responds to changing market demands. This could become important as your organization introduces new data sources, adapts to additional privacy regulations, or encounters emerging security threats.
IRI has provided data masking technology since 2007 and continues to develop solutions for protecting sensitive information. To discuss your data masking requirements or initiate a proof of concept, contact If you would like to exchange information or initiate a POC, contact info@iri.com or learn more at IRI Data Masking Solutions.
Frequently Asked Questions (FAQs)
What is a data masking tool and why is it important?
A data masking tool protects sensitive information by replacing original values with realistic, fictional, or obfuscated data. This helps preserve data utility while reducing the risk of exposing confidential information. Data masking is important for protecting privacy, supporting regulatory compliance, and enabling safer use of data in software testing, analytics, and research environments.
How do I know what data needs to be masked?
Start by assessing the types of data your organization collects and processes, where it is stored, and who uses it. Identify whether the data is structured (databases, spreadsheets), semi-structured (NoSQL databases, EDI files), or unstructured (text files, images, documents). Then determine whether it contains personally identifiable information (PII), protected health information (PHI), or other sensitive values subject to privacy regulations such as GDPR or HIPAA.
How should sensitive data be masked?
The appropriate masking method depends on your business requirements, compliance obligations, and how the protected data will be used. For example, you may need irreversible redaction to remove sensitive information, reversible encryption for authorized re-identification, or deterministic masking to preserve referential integrity across tables and systems. The chosen technique should balance data protection with the utility required for testing, analytics, or operational workflows.
What factors should I consider when choosing a data masking tool?
Key evaluation criteria include sensitive data discovery capabilities, supported masking techniques, scalability, processing performance, integration with existing systems, compliance support, audit logging, and overall cost. The tool should support your required data sources, provide manageable workflows, and produce consistent masking results across relevant environments.
How can I evaluate the performance of a data masking tool?
Evaluate how efficiently the tool processes large datasets, supports parallel processing, and integrates with your existing infrastructure. A proof-of-concept (POC) trial or pilot program allows you to mask representative datasets and assess processing speed, accuracy, and usability before making a purchasing decision. Vendors such as IRI offer POC opportunities to help organizations evaluate masking performance under their specific operating conditions.
What compliance requirements should a data masking tool support?
A data masking tool should support applicable privacy regulations and industry standards, including GDPR, HIPAA, CCPA, and PCI DSS. Relevant capabilities may include discovering and masking regulated information, helping address Data Subject Access Requests (DSARs), such as the right to erasure, and maintaining detailed discovery and job audit logs. These functions can support compliance efforts and provide documentation for regulatory audits.
Can a data masking tool work with both on-premise and cloud environments?
Yes. Many data masking solutions support both on-premises and cloud-based environments. Tools such as IRI FieldShield and DarkShield can help organizations discover and mask sensitive information across hybrid or multi-cloud infrastructures while supporting data protection requirements within their established security boundaries.
How can data masking tools integrate into DevOps pipelines?
Data masking tools that support command-line execution, APIs, and automated workflows can be integrated into continuous integration and continuous delivery (CI/CD) pipelines. This allows organizations to automate masking of updated datasets, maintain protected test environments, and reduce manual processing that could otherwise delay testing and deployment cycles.
What are the cost considerations for data masking tools?
Consider the total cost of ownership, including software licensing, technical support, customization, maintenance, and future upgrades. Evaluate whether these expenses align with your organization’s budget and expected return on investment (ROI), particularly when masking requirements involve large data volumes, multiple platforms, or enterprise-wide deployment.
Can IRI provide proof-of-concept or pilot programs for data masking?
Yes. IRI offers proof-of-concept (POC) evaluations and pilot programs that allow organizations to test data masking capabilities using representative datasets. These evaluations help assess processing speed, masking accuracy, usability, and integration with existing infrastructure before committing to a full deployment.