FieldShield vs. DarkShield for RDB Masking
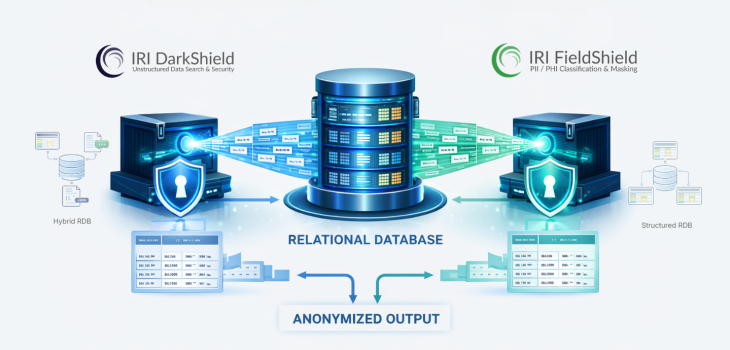
The IRI Voracity Data Management platform and the IRI Data Protector suite provide robust data masking tools for finding and anonymizing sensitive data in different environments. When working with relational database (RDB) sources, however, two key IRI products come into play: FieldShield and DarkShield.
Both tools have the same pricing for RDB use and share the same front-end IRI Workbench GUI. Both also use the same data classes and masking functions to secure personally identifiable information (PII) and other sensitive data in database environments. However, they differ somewhat in functional scope, discovery capabilities, runtime engines, and job configurations.
Functional Comparison Matrix
The following overview highlights the key differences between FieldShield and DarkShield.
| Feature/Aspect | FieldShield | DarkShield |
| Primary Focus | Structured data masking in relational databases | Discovery and masking across structured and semi/unstructured RDB columns |
| Data Types Supported | Strictly structured fields (tables, columns) | Structured fields plus semi/unstructured text or files in RDB columns |
| Discovery Capabilities | Data classification (search) is performed before masking, though it uses the same data classes and masking rules as DarkShield. Limited to metadata (location-based) matchers for discovery. | Simultaneous search and masking of sensitive data in a schema using the same data classes and masking functions as FieldShield. Uses location and/or data (content) matchers as needed. |
| Masking Methods | Deterministic, encryption, pseudonymization, redaction, etc. | Same masking methods, extended to free-text and mixed data formats |
| Integration | Deep integration with Voracity ETL via the use of the CoSort SortCL syntax and program for its masking jobs | Supported in Voracity, can create SortCL DDF for textual ETL use, but uses a REST API for search/mask |
| Ease of Use | Requires schema knowledge and more setup steps | Wizard-driven GUI in IRI Workbench for RDB masking jobs (search + mask simultaneously) |
| Audit & Logging | Produces an audit trail of search results and masking job details; integrates with CoSort V11 OGS logging | Enhanced audit logs for discovery and masking jobs across mixed RDB columns |
| Best Fit | Structured relational database environments with well-defined schemas | Hybrid environments where sensitive data may reside in both structured and semi/unstructured RDB columns |
Use Case Matrix
The way an environment stores data may favor one tool over the other.
| Use Case Type | Best Tool | Example Scenario |
| Classic RDB Masking | FieldShield | Masking SSNs in a customer table with a defined schema with advanced business logic |
| Hybrid RDB Masking | DarkShield | Searching and masking PII in free-text notes stored in VARCHAR columns amid complex constraints |
| Compliance (GDPR, HIPAA) | Both | Ensuring sensitive fields are anonymized before reporting and DevOps |
| Data Discovery | DarkShield | Automatically finding sensitive data in unexpected RDB columns during masking |
| ETL Integration | FieldShield | Applying masking during ETL workflows for structured, anonymized data warehouse loads |
| Audit & Governance | Both | FieldShield produces detailed audit trails (including CoSort V11 OGS logs); DarkShield provides extended discovery and masking logs as well |
| Operational Oversight | Both | Tracking search results, masking jobs, data recovery, and compliance reporting |
Decision Flowchart
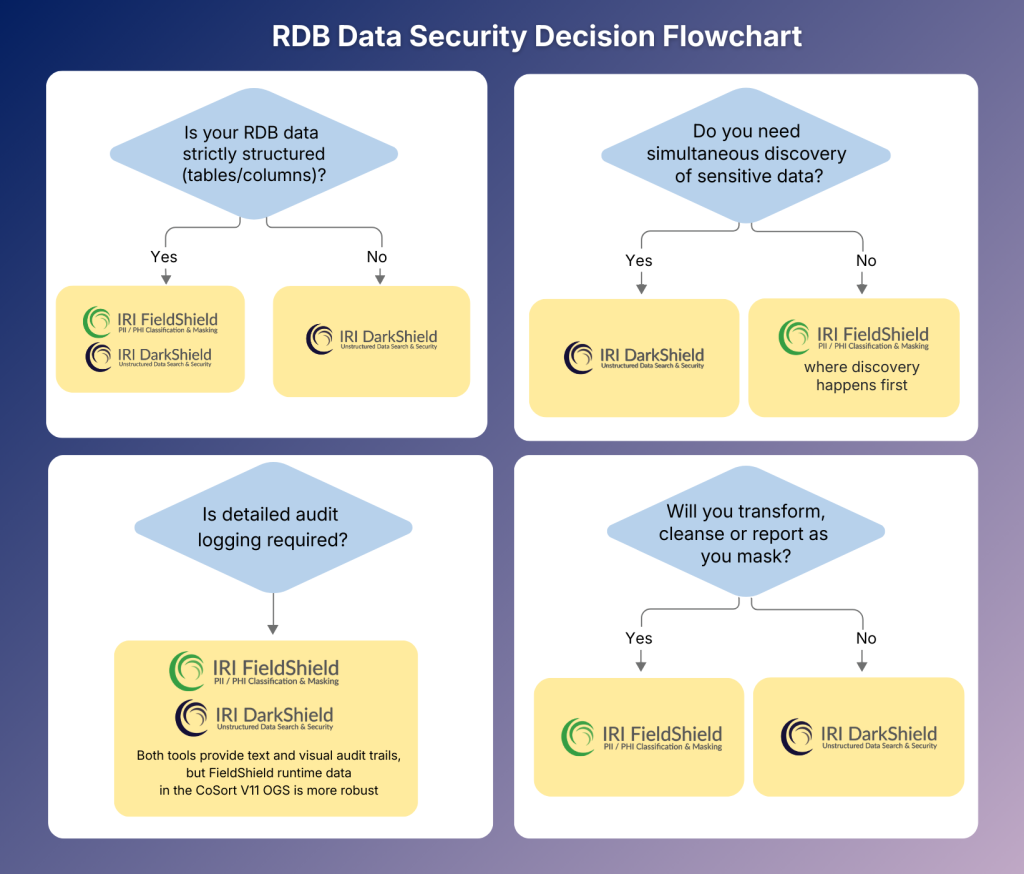
Here’s a simple guide for choosing between FieldShield and DarkShield in RDB contexts:
Conclusion
- FieldShield is ideal for structured RDB environments and complex business logic where teams know the sensitive fields. Teams can apply masking before or during Voracity ETL or BI/AI workflows. FieldShield data classes and functions also work with data quality and synthesis functions, as well as with IRI Ripcurrent CDC jobs.
- DarkShield is best for hybrid RDB environments containing semi/unstructured text and/or complex constraints. It is especially useful when teams need to discover sensitive data while masking it for high-volume search and masking efficiency.
- Both tools support data privacy, compliance, and governance. FieldShield also integrates with CoSort V11’s OGS logging environment for detailed audit trails. Both tools can subset and mask RDB data for use in lower environments or test schemas.
Both FieldShield and DarkShield are included in the IRI Voracity data management platform, which also supports RowGen, CoSort, NextForm, Ripcurrent, FACT, and more. Please email info@iri.com if you have any questions or would like more information.
Frequently Asked Questions
What is the main difference between IRI FieldShield and DarkShield for relational database masking?
FieldShield focuses on structured relational database masking and works well when teams already know which fields contain sensitive data. DarkShield supports structured data as well, but it is better suited to environments where sensitive data may also appear in semi-structured or unstructured content stored in database columns. IRI
Which tool is better for discovering sensitive data during masking?
DarkShield is generally the better fit when discovery needs to happen during masking. It can use both location-based and content-based matchers to find sensitive data, including PII in unexpected or mixed-content columns. FieldShield relies more on predefined structured locations and metadata-based discovery. IRI
Which tool is better for ETL-integrated masking?
FieldShield is the stronger fit for masking within ETL workflows because it integrates with Voracity through SortCL syntax and runtime processing. DarkShield can participate in Voracity workflows, but it uses a REST API for search and masking operations. IRI
Do FieldShield and DarkShield use the same masking methods?
Yes. Both products use the same IRI data classes and masking functions for protecting sensitive data. The main difference is where and how they apply those capabilities, particularly when dealing with structured versus semi-structured or unstructured data in relational databases.